THE IDEA
Noise in, picture out
In training, noise is added to images bit by bit until the picture is destroyed. The model learns to reverse each small step.
See the steps
WHAT THE RESEARCH SAYS
NOISE to picture, step by step
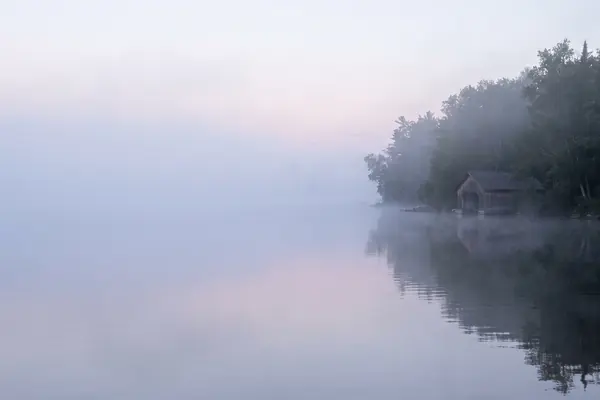
AI-generated image, not a photograph of a real person or place.
Every AI picture starts as static.
Most text-to-image tools use diffusion models. They learn to remove noise from images, so they can start from pure noise and clear it, step by step, into something that matches your words.
THE SHORT ANSWER
Diffusion models learn by wrecking pictures with noise
and practicing how to put them back.
THE IDEA
In training, noise is added to images bit by bit until the picture is destroyed. The model learns to reverse each small step.
See the stepsTHE TRAINING
One open dataset, LAION-5B, holds 5.85 billion image-text pairs, used to train and fine-tune models including Stable Diffusion.
See the numbersTHE COST
Researchers measured image generation as the most energy-hungry of the AI tasks they tested.
Compare tasks
FOUR STEPS, IN PLAIN LANGUAGE
The math is heavy, but the idea is simple enough to explain at the kitchen table.
Models train on huge sets of images paired with text, such as the 5.85 billion pairs in LAION-5B.
Training adds small amounts of noise to an image, step after step, until no signal is left.
The model learns to undo one small step of noise at a time, which is why it is called denoising.
To make a new image it starts from noise. Cross-attention layers let your text guide every cleanup step.
TWO NUMBERS WORTH KNOWING
One number on what models learn from,
one on what it costs to make pictures.
5.85 billion
Image-text pairs in one open dataset
Of these, 2.32 billion have English captions. The authors used the dataset to replicate and fine-tune models including CLIP, GLIDE and Stable Diffusion.
TRAINING DATA · LAION-5B
60× more
Image vs text generation, on average
Image generation used, on average, over 60 times more energy than text generation: 2.9 kWh against 0.047 kWh per 1,000 runs.
ENERGY · POWER HUNGRY PROCESSING
The latent diffusion paper behind Stable Diffusion notes that training diffusion models directly on pixels often takes hundreds of GPU days, which is why it works in a compressed latent space instead.
A QUICK ENERGY CHECK
Pick an AI task to see how much electricity 1,000 runs used in a 2023 study. The bar shows how energy-hungry the task is.
Figures from Luccioni, Jernite and Strubell, Power Hungry Processing (2023), measured per 1,000 inferences. A smartphone charge is about 0.022 kWh.
WHY IT GOT FASTER
Early diffusion models worked on every pixel, which made training and image-making slow and expensive.
Latent diffusion, the approach behind Stable Diffusion, first squeezes images into a compact representation with an autoencoder, runs the noise-and-cleanup there, then turns the result back into pixels. The authors say this greatly reduces the computing needed.
In conversation
A kind of AI model trained to reverse a process that gradually adds noise to images until the picture is destroyed. Running it backwards from pure noise produces a new image.
In latent diffusion models, cross-attention layers let a text prompt guide the denoising, so the picture that emerges matches the description.
Large collections of images paired with text. LAION-5B, one open dataset, contains 5.85 billion image-text pairs, 2.32 billion of them in English.
More than most AI tasks. A 2023 study measured a mean of 2.9 kWh per 1,000 images, over 60 times the average for text generation, with big differences between models.
Not from a prompt alone. In January 2025 the US Copyright Office concluded that prompts do not alone provide sufficient control. Your own artwork that shows in the output, or creative selection, arrangement or changes to outputs, can be protected.
Each figure on this page comes from the sources below.
ABOUT THIS NAME
aifunphoto.com is part of the DoodleSale portfolio. It isn't in an auction right now, but you can ask about leasing it.